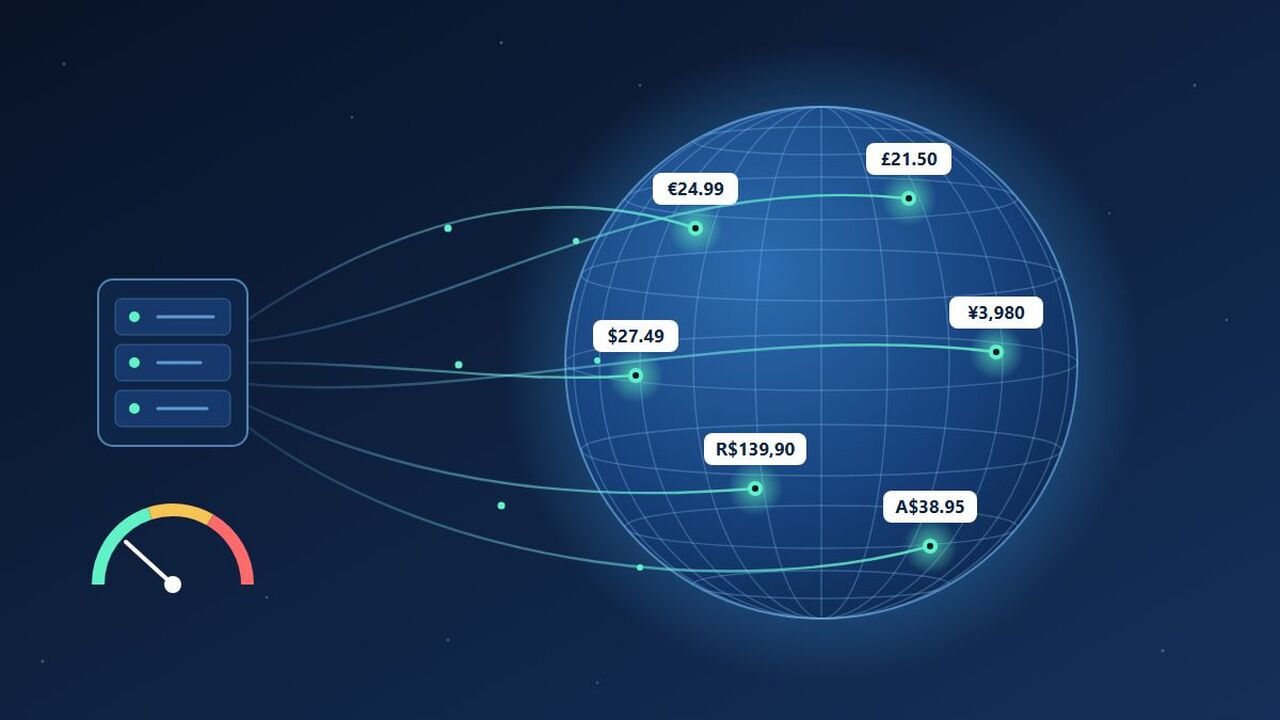
Pull up the same product page from New York and from Munich and there’s a good chance you’ll see two different prices, two different stock levels, and maybe a banner telling one of you the item doesn’t ship to your region. Search results shift from city to city. Ads change by country. Delivery fees and hotel rates move depending on which postcode the site thinks you’re in.
That’s why so many teams collect geo-specific data for price intelligence, SEO rank tracking, ad verification, market research and travel fare monitoring. It’s also why so many of them run straight into rate limits. The site sees hundreds of requests arriving from one address, or from a block of addresses that obviously belongs to a cloud provider, and it starts throttling, throwing CAPTCHAs, or quietly handing back something other than what a local visitor would see.
The good news is that most rate limiting problems in geo data collection come down to a handful of fixable mistakes. Here’s how to set up a collection job that gets local results and keeps getting them.
Why location makes rate limiting worse
Ordinary scraping already has to deal with request limits. Location adds two complications.
First, the request has to come from the right place. That rules out the easy trick of spreading traffic over whatever IPs you have lying around. If you need prices as they appear in Lyon, an IP in Virginia is useless no matter how clean it is.
Second, the pool of usable IPs shrinks as your targeting gets tighter. Ten thousand requests spread across an entire country is one thing. The same volume squeezed into a single city means each IP carries far more of the load, and per-IP limits kick in much sooner.
How sites actually rate limit you
It helps to know what you’re up against. Most sites track some combination of:
-
Requests per IP address over a time window
-
Requests per session or cookie
-
Requests per account or API key, if you’re logged in
-
Behavioral signals, like hitting pages at perfect one-second intervals or never loading images and scripts
The polite version of a rate limit is an HTTP 429 “Too Many Requests” response, sometimes with a Retry-After header telling you how long to wait. That’s the easy case, because at least you know where you stand.
The harder cases are silent. Some sites return a normal 200 status with an empty results list, a stripped-down page, or the content for a default location instead of the one you asked for. If you only check status codes, you can collect a week of “data” that’s really a week of fallback pages. Keep that in mind, because we’ll come back to it.
Step 1: Decide how precise your location needs to be
Before you touch any tooling, write down the level of location your data truly depends on.
Country level is enough for a lot of jobs, such as checking whether a streaming catalog or a software subscription is priced differently in Germany and Brazil. City level matters for local search results, delivery apps, ride pricing and anything tied to store inventory. Some jobs go further still and need a specific internet provider, which comes up in ad verification when campaigns are targeted at one ISP’s customers.
This matters for rate limits because the more precise your targeting, the smaller the set of IPs you’re drawing from. Don’t ask for city-level targeting when country level gives you the same answer. You’ll get a deeper pool and spread the load further.
Step 2: Route traffic through a residential proxy network
Datacenter proxies are fast and cheap, and for some targets they’re perfectly fine. On geo-sensitive sites they tend to cause two problems. Their IP ranges are registered to hosting companies, so many sites recognize them and apply stricter limits from the very first request. And their location can be unreliable, since datacenter IPs are sometimes geolocated to the hosting company’s registered address rather than the city they were sold as.
Residential IPs are assigned by consumer internet providers to real households, so a request through one looks like an ordinary visitor from that area. A large residential proxy network gives you two things at once: IPs that sit in the places you need, and enough of them that no single address has to carry much traffic. ProxyEmpire’s rotating residential proxies, for example, draw on a pool of 30M+ IPs across 170+ countries with country, region, city and ISP targeting, so you can match each request to its market without funneling everything through a handful of exits.
When you compare providers, look at pool depth in the specific cities you care about rather than the headline total. A big global number doesn’t help much if your target city only has a few hundred IPs online at any given moment.
Step 3: Match rotation to the task
Rotation is where a lot of people trip themselves up, usually by rotating too much or too little.
Rotating on every request suits stateless pages: search results, individual product pages, public listings. Each request goes out on a fresh IP, so per-IP counters barely move.
Sticky sessions suit anything with state. Maybe you’re paginating through results that depend on a session cookie, adding an item to a cart to reveal the final price with local tax and shipping, or stepping through a multi-page booking form. Switching IP halfway through looks odd. To the site, a visitor who teleports from one suburb to another between page two and page three is a red flag. Keep the same IP for the whole flow, then rotate before the next one.
A simple rule of thumb: one logical visit, one IP.
Step 4: Slow down on purpose
Rotation spreads requests out. It doesn’t give you permission to hammer a site. The jobs that run cleanly for months are the ones that pace themselves.
A few habits that help:
-
Cap concurrency per target domain, not just globally. Ten workers spread across ten sites is gentle. Ten workers on one small regional retailer is not.
-
Add random jitter between requests. Real people don’t click at exact one-second intervals.
-
Respect Retry-After when you get it, and back off exponentially when you don’t.
-
Treat a spike in errors as a reason to slow the whole job down, not as a reason to retry faster.
Here’s a minimal Python example of that retry logic:
import random
import time
import requests

# Gateway details come from your proxy provider's dashboard
PROXY = "http://USERNAME:PASSWORD@GATEWAY_HOST:PORT"

def fetch(url, lang="de-DE,de;q=0.9", max_tries=5):
delay = 2
for attempt in range(max_tries):
r = requests.get(
url,
proxies={"http": PROXY, "https": PROXY},
headers={"Accept-Language": lang},
timeout=30,
)
if r.status_code != 429 and r.status_code < 500:
return r
retry_after = r.headers.get("Retry-After", "")
wait = int(retry_after) if retry_after.isdigit() else delay
time.sleep(wait + random.uniform(0, 1.5))
delay *= 2
return None
Nothing fancy, but it already beats the most common approach, which is retrying instantly in a tight loop until the IP gets banned.
Step 5: Make the rest of the request agree with the IP
An IP in Madrid paired with a US English Accept-Language header, a New York time zone in the browser and a dollar currency cookie left over from an earlier session tells a confusing story. Some sites resolve that by showing the default version of the page. Others treat it as suspicious.
Set Accept-Language to match the market. If you use a headless browser, set the time zone and locale as well. Clear cookies between locations, or keep a separate cookie jar per region, so a store or currency preference from one market doesn’t leak into the next.
Also check whether the site lets visitors choose a location or type in a postcode. On some delivery and grocery sites, that selection decides what you see as much as the IP does, so your scraper needs to set it the same way a local shopper would.
Step 6: Don’t fetch what you already have
The cheapest request is the one you never send. Cache pages that change slowly, dedupe URLs before they reach the queue, and schedule each source by how often its data actually moves. Hotel rates for next weekend might change several times a day. A product’s spec sheet might not change for a year.
Where a site supports them, conditional requests using ETag or If-Modified-Since headers let the server reply with a short 304 Not Modified instead of the full page, which saves bandwidth on both ends. Cutting volume like this often does more for rate limits than any clever rotation scheme.
Step 7: Check that you got the location you asked for
Remember those silent failures. Build checks into the pipeline that confirm each response is genuinely local:
-
Look for the currency, language or store names that should appear for that market
-
Log the exit IP and its reported location for a sample of requests
-
Spot-check a few results by hand every week
When a check fails, flag the batch instead of storing it. Bad geo data is worse than missing data, because sooner or later someone will make a pricing or campaign decision based on it.
Step 8: Stay on the right side of the line
Collecting public data at a reasonable pace is standard practice, but it still pays to be careful. Read the site’s terms and its robots.txt, stay out of logged-in areas unless you have permission, and keep personal data out of your scrapes unless you have a lawful basis to process it under rules like GDPR. It’s also worth choosing a provider that’s open about how its residential IPs are sourced. Responsible collection happens to be sustainable collection too: jobs that behave well get blocked less.
A quick checklist
-
Pick the least precise location level that still answers your question
-
Use residential IPs in the target market, from a pool deep enough for your volume
-
Rotate per request for stateless pages, and keep a sticky session for multi-step flows
-
Cap concurrency per domain and add jitter
-
Honor 429s and Retry-After, and back off exponentially
-
Match language, time zone and cookies to the location
-
Cache, dedupe and use conditional requests
-
Validate that every batch is truly local before you store it
Rate limits aren’t really the enemy here. They’re the site’s way of telling you your traffic doesn’t look like its normal visitors. Get the location right, spread the load across a proper residential proxy network, pace yourself, and make every part of the request tell the same story. Do that, and most of the blocking stops being a problem.
About the author
Zlata Kotomkina works as a Marketing Manager for ProxyEmpire. She attended Dublin Business School and studied Digital Marketing & Analytics.